What is universal information extraction?
Universal information extraction is a capability that enables key information extraction from any document type. Unlike prebuilt information extraction, which requires fine-tuning for specific document types, universal information extraction can process and extract key information from any random document without additional training or customization.
Why use Upstage Information Extract?
- Works with any document type: Supports complex PDFs, scanned images, and Microsoft Office documents, ensuring seamless data extraction across various formats.
- Schema-agnostic processing: Can dynamically process and generate structured outputs based on any given schema, enabling on-demand customization for different use cases.
- Extracts hidden and implied information: Can extract not only explicitly stated information but also implied or inferred values, such as determining the total amount from multiple line items or identifying key details that aren’t directly labeled in the document.
- No fine-tuning required: Extracts relevant data without predefined templates or additional model training.
What models does Upstage provide?
| Alias | Currently points to | RPS (Learn more) |
|---|---|---|
| information-extract | information-extract-260904 | 1 (Sync) / 2 (Async) |
| information-extract-260610 | 1 (Sync) / 2 (Async) | |
| information-extract-260304 | 1 (Sync) / 2 (Async) | |
| information-extract-nightly | - | 1 (Sync) / 2 (Async) |
information-extract-260610 and information-extract-260304 will reach end of service on October 6, 2026 (KST). Requests naming them will return an error after that date — please migrate to information-extract-260904 or the information-extract alias before then.
Extract Key Information in Upstage Studio!

Sending a request in three simple steps
The Upstage Information Extract API is designed to follow OpenAI Chat Completion API's request and response formats. Users can use the OpenAI SDK to structure requests and handle responses accordingly.
Add input files to messages
You can input a single file, which should be provided as URL or base64 encoded string in the messages field, formatted as follows:
Requirements for the input file are:
- Supported file formats: JPEG, PNG, BMP, PDF, TIFF, HEIC, DOCX, PPTX, XLSX, HWP, HWPX
- Maximum file size: 50MB
- Maximum number of pages per file: 100 pages
- Maximum pixels per page: 200,000,000 pixels. (For non-image files, the number of pixels is determined after converting the file to images at 150 DPI.)
- Supported character sets: Alphanumeric, Hangul, Hanja, Katakana, and Hiragana are supported. Hanzi and Kanji are in beta versions, which means they are available but not fully supported.
Examples
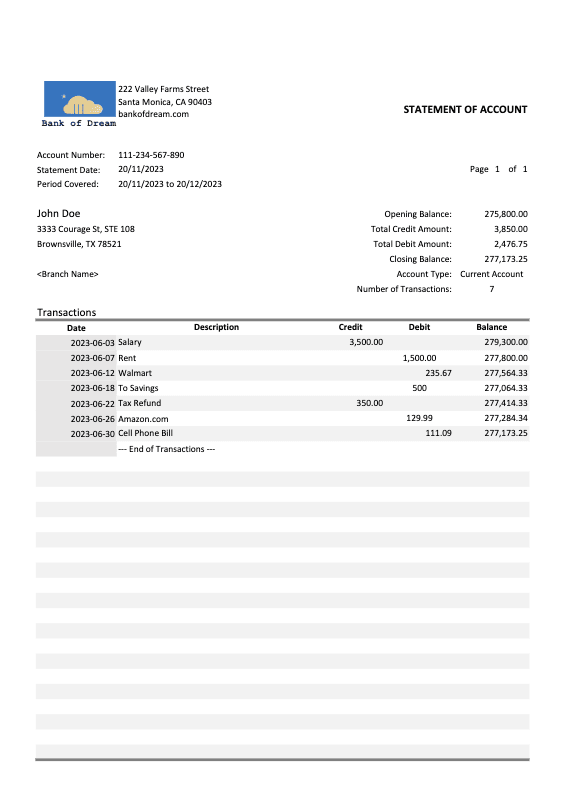
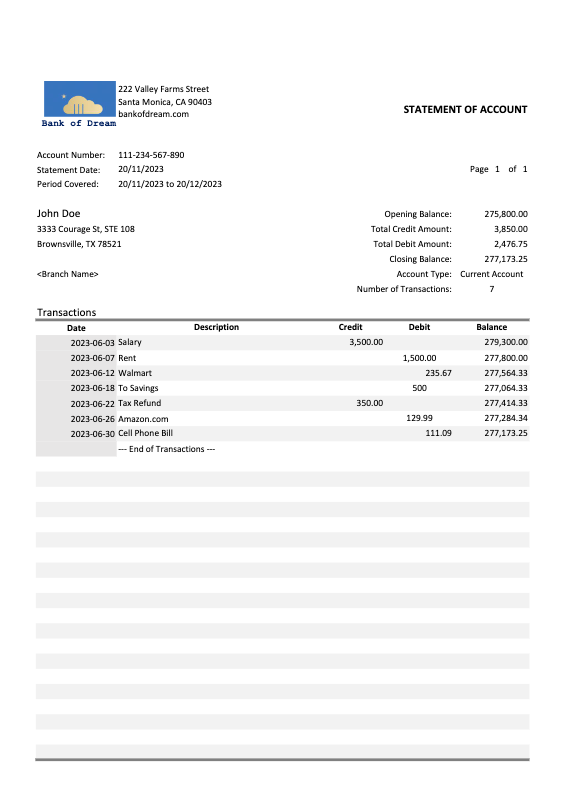
bank_statement.png
Simple extraction
Extract structured information from documents using a defined JSON schema.
Request
Response
Extraction modes (Beta)
Extract information from documents using different extraction modes.
- Standard (
mode: "standard") is the default extraction mode that provides fast and accurate extraction for most document types. - Enhanced (
mode: "enhanced") is the extraction mode that offers improved robustness for challenging documents:- Complex tables: Better handling of nested tables, merged cells, and irregular table structures
- Poor quality scans: Improved extraction from low-resolution or degraded document scans
- Handwritten text: Enhanced recognition of handwritten content
Enhanced mode incurs additional costs. See the pricing page for details.
Request
Extract Key Information in Upstage Studio!
Frequently Asked Questions
Check out frequently asked questions below. For more FAQs, visit the FAQ page.