Deprecation notice
Prebuilt Information Extraction was deprecated on May 6, 2026. Please use Universal extraction instead.
What is prebuilt information extraction?
Built on highly accurate Document OCR, Upstage's prebuilt information extraction models excel at identifying and extracting predefined key information within specific documents types. Prebuilt information extractors are ideal for automating repetitive tasks--such as data entry, compliance checks, or invoice processing, where specific fields must be extracted consistently and accurately with large throughput.
Why use Upstage prebuilt information extractors?
- Tailored for specific document types: Unlike universal information extraction models, Upstage prebuilt information extractors are fine-tuned for specific document formats, achieving higher accuracy, typically around 90-95% for tens to hundreds of keys. This level of precision makes them ideal for processing documents with monetary values, such as invoices, receipts, contracts, forms, and financial reports, where capturing accurate information is essential for automating processes.
- High robustness for documents in the wild: Our prebuilt information extractors handle challenging document conditions, including rotated images, watermarks, noise, and checkboxes, ensuring reliable performance even with imperfect or low-quality inputs.
- Seamless integration: Designed for enterprise applications, our extractors provide structured outputs in JSON format, making it easy to integrate into existing automation pipelines, databases, and business workflows.
What models does Upstage provide?
Receipt
| Sample document |  |
| Alias | receipt-extraction |
| Currently points to | receipt-extraction-3.2.0 |
| RPS (Learn more) | 1 |
Logistics documents
| Sample document |  |  |  |
| Alias | air-waybill-extraction | bill-of-lading-and-shipping-request-extraction | bill-of-lading-and-shipping-request-extraction |
| Currently points to | air-waybill-extraction-250415 | bill-of-lading-and-shipping-request-extraction-250415 | bill-of-lading-and-shipping-request-extraction-250415 |
| RPS (Learn more) | 1 | 1 | 1 |
| Sample document | 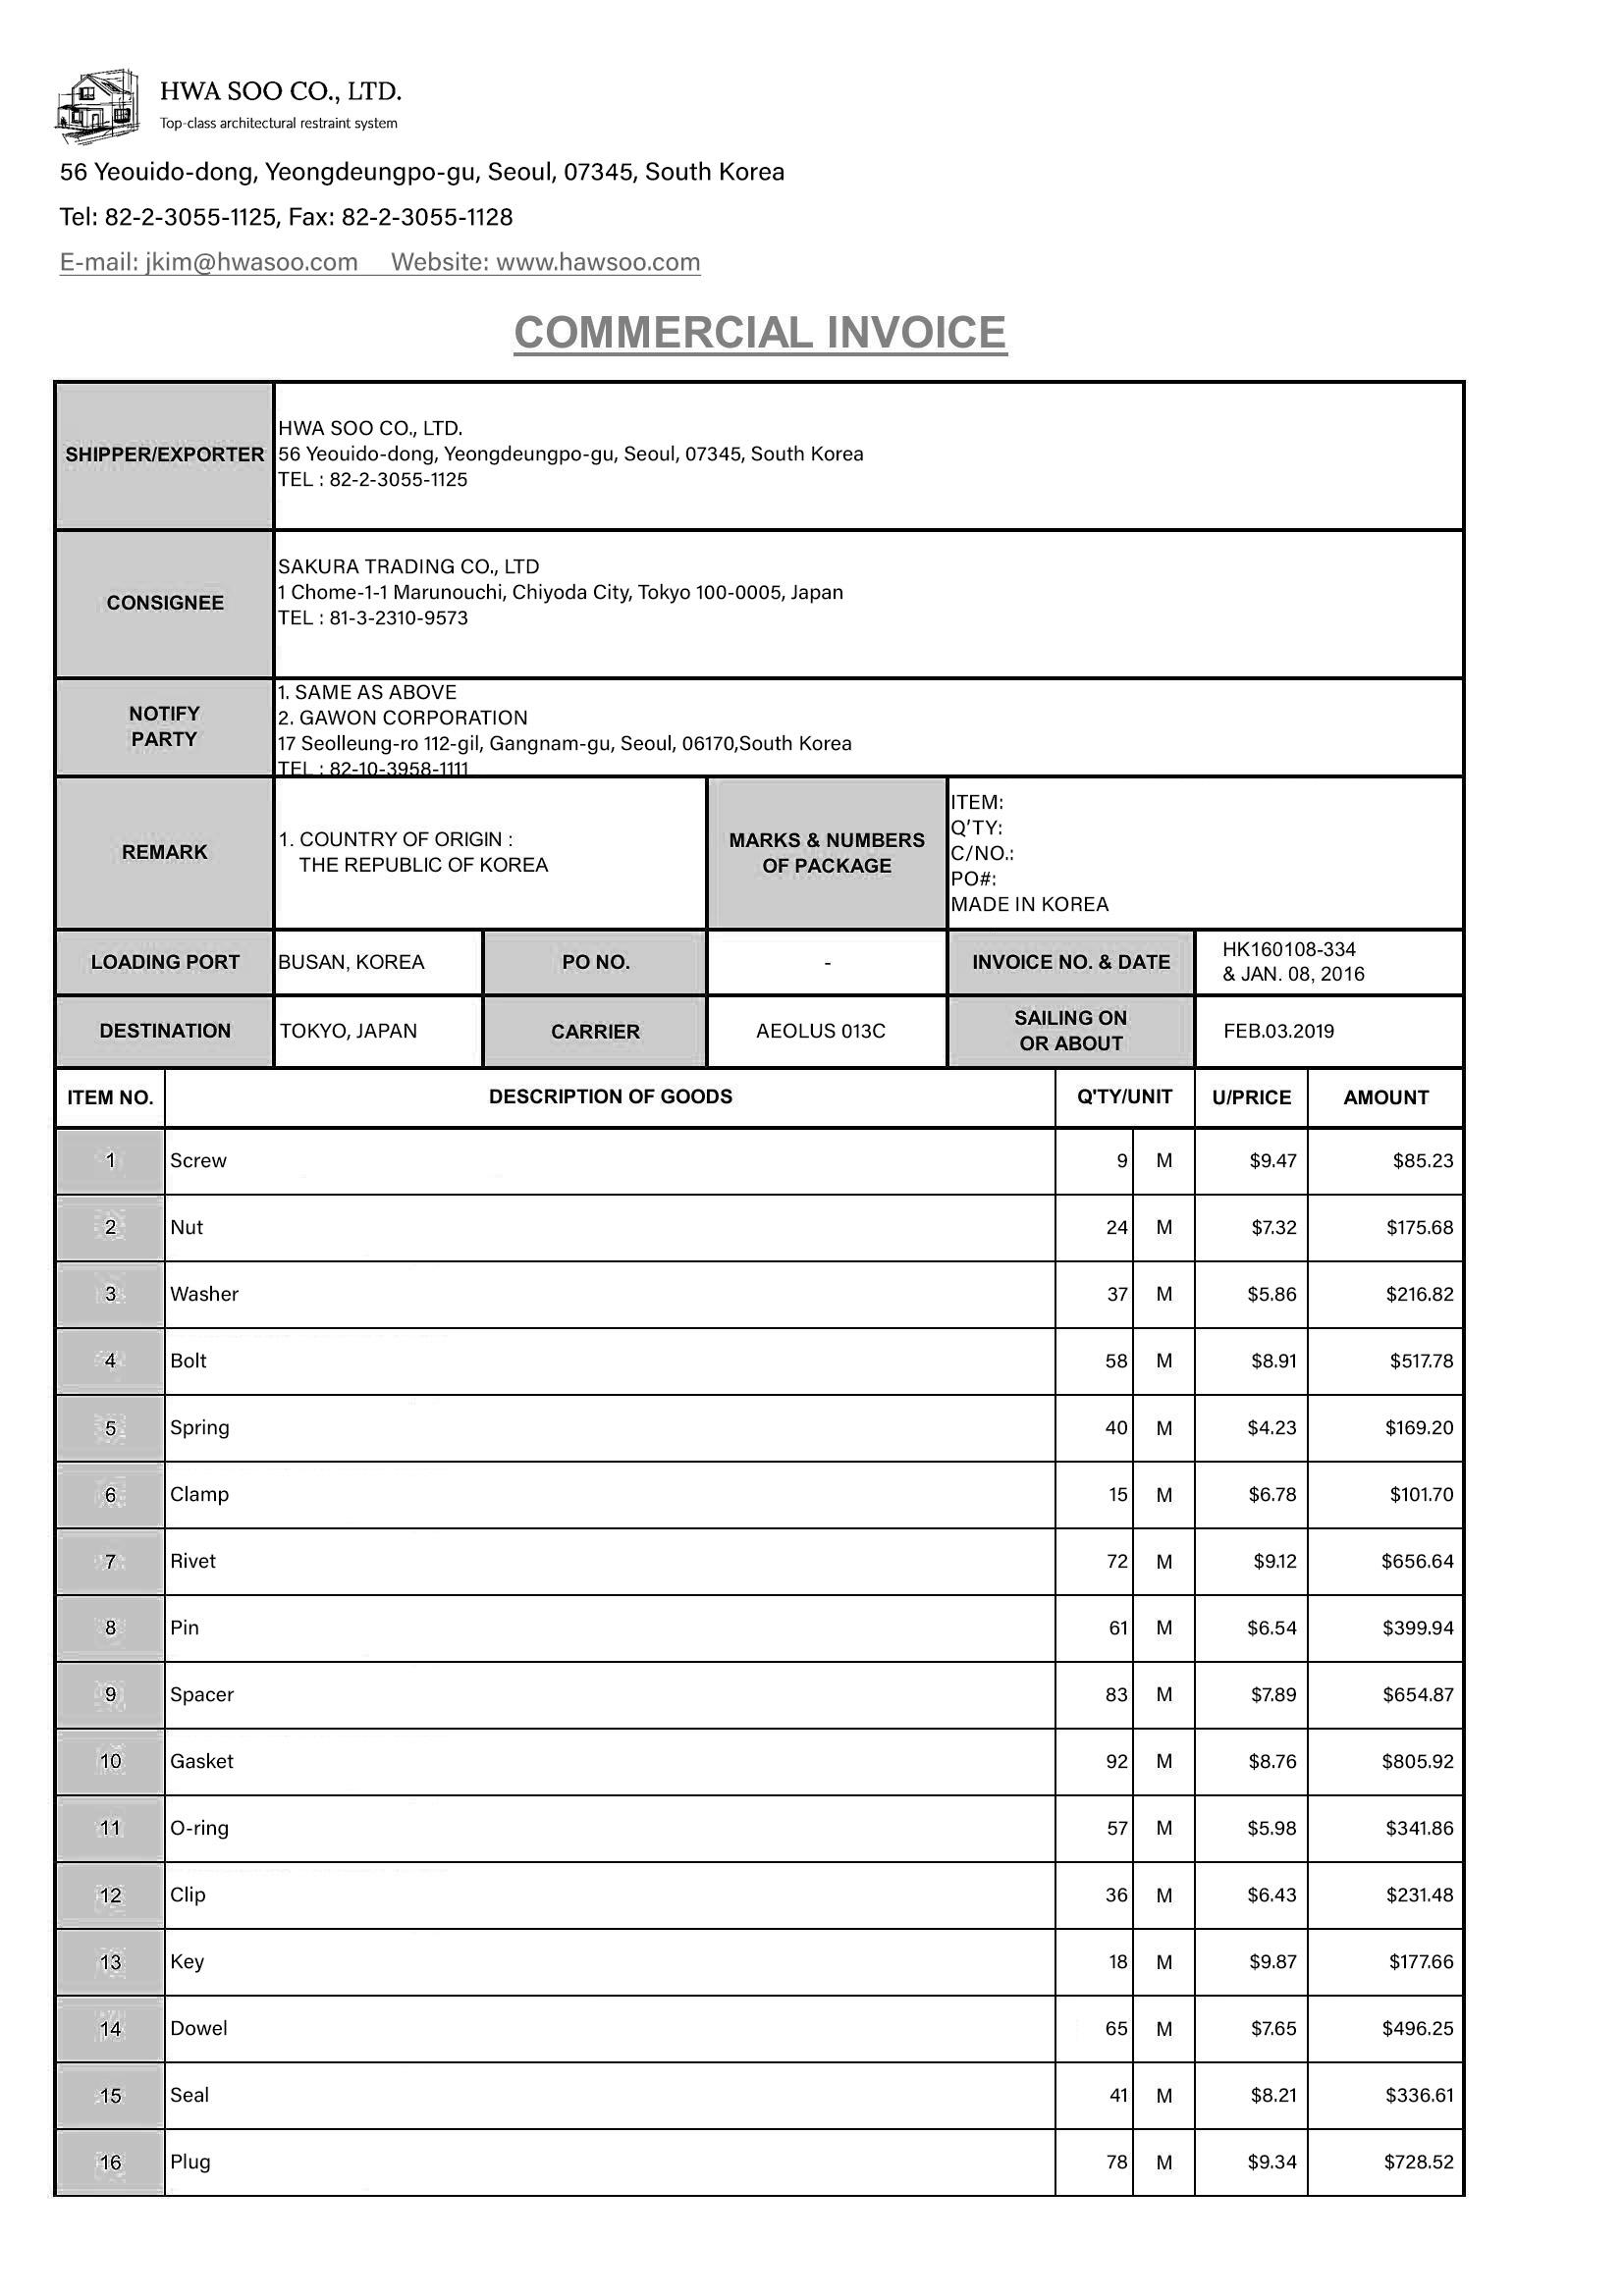 |  | 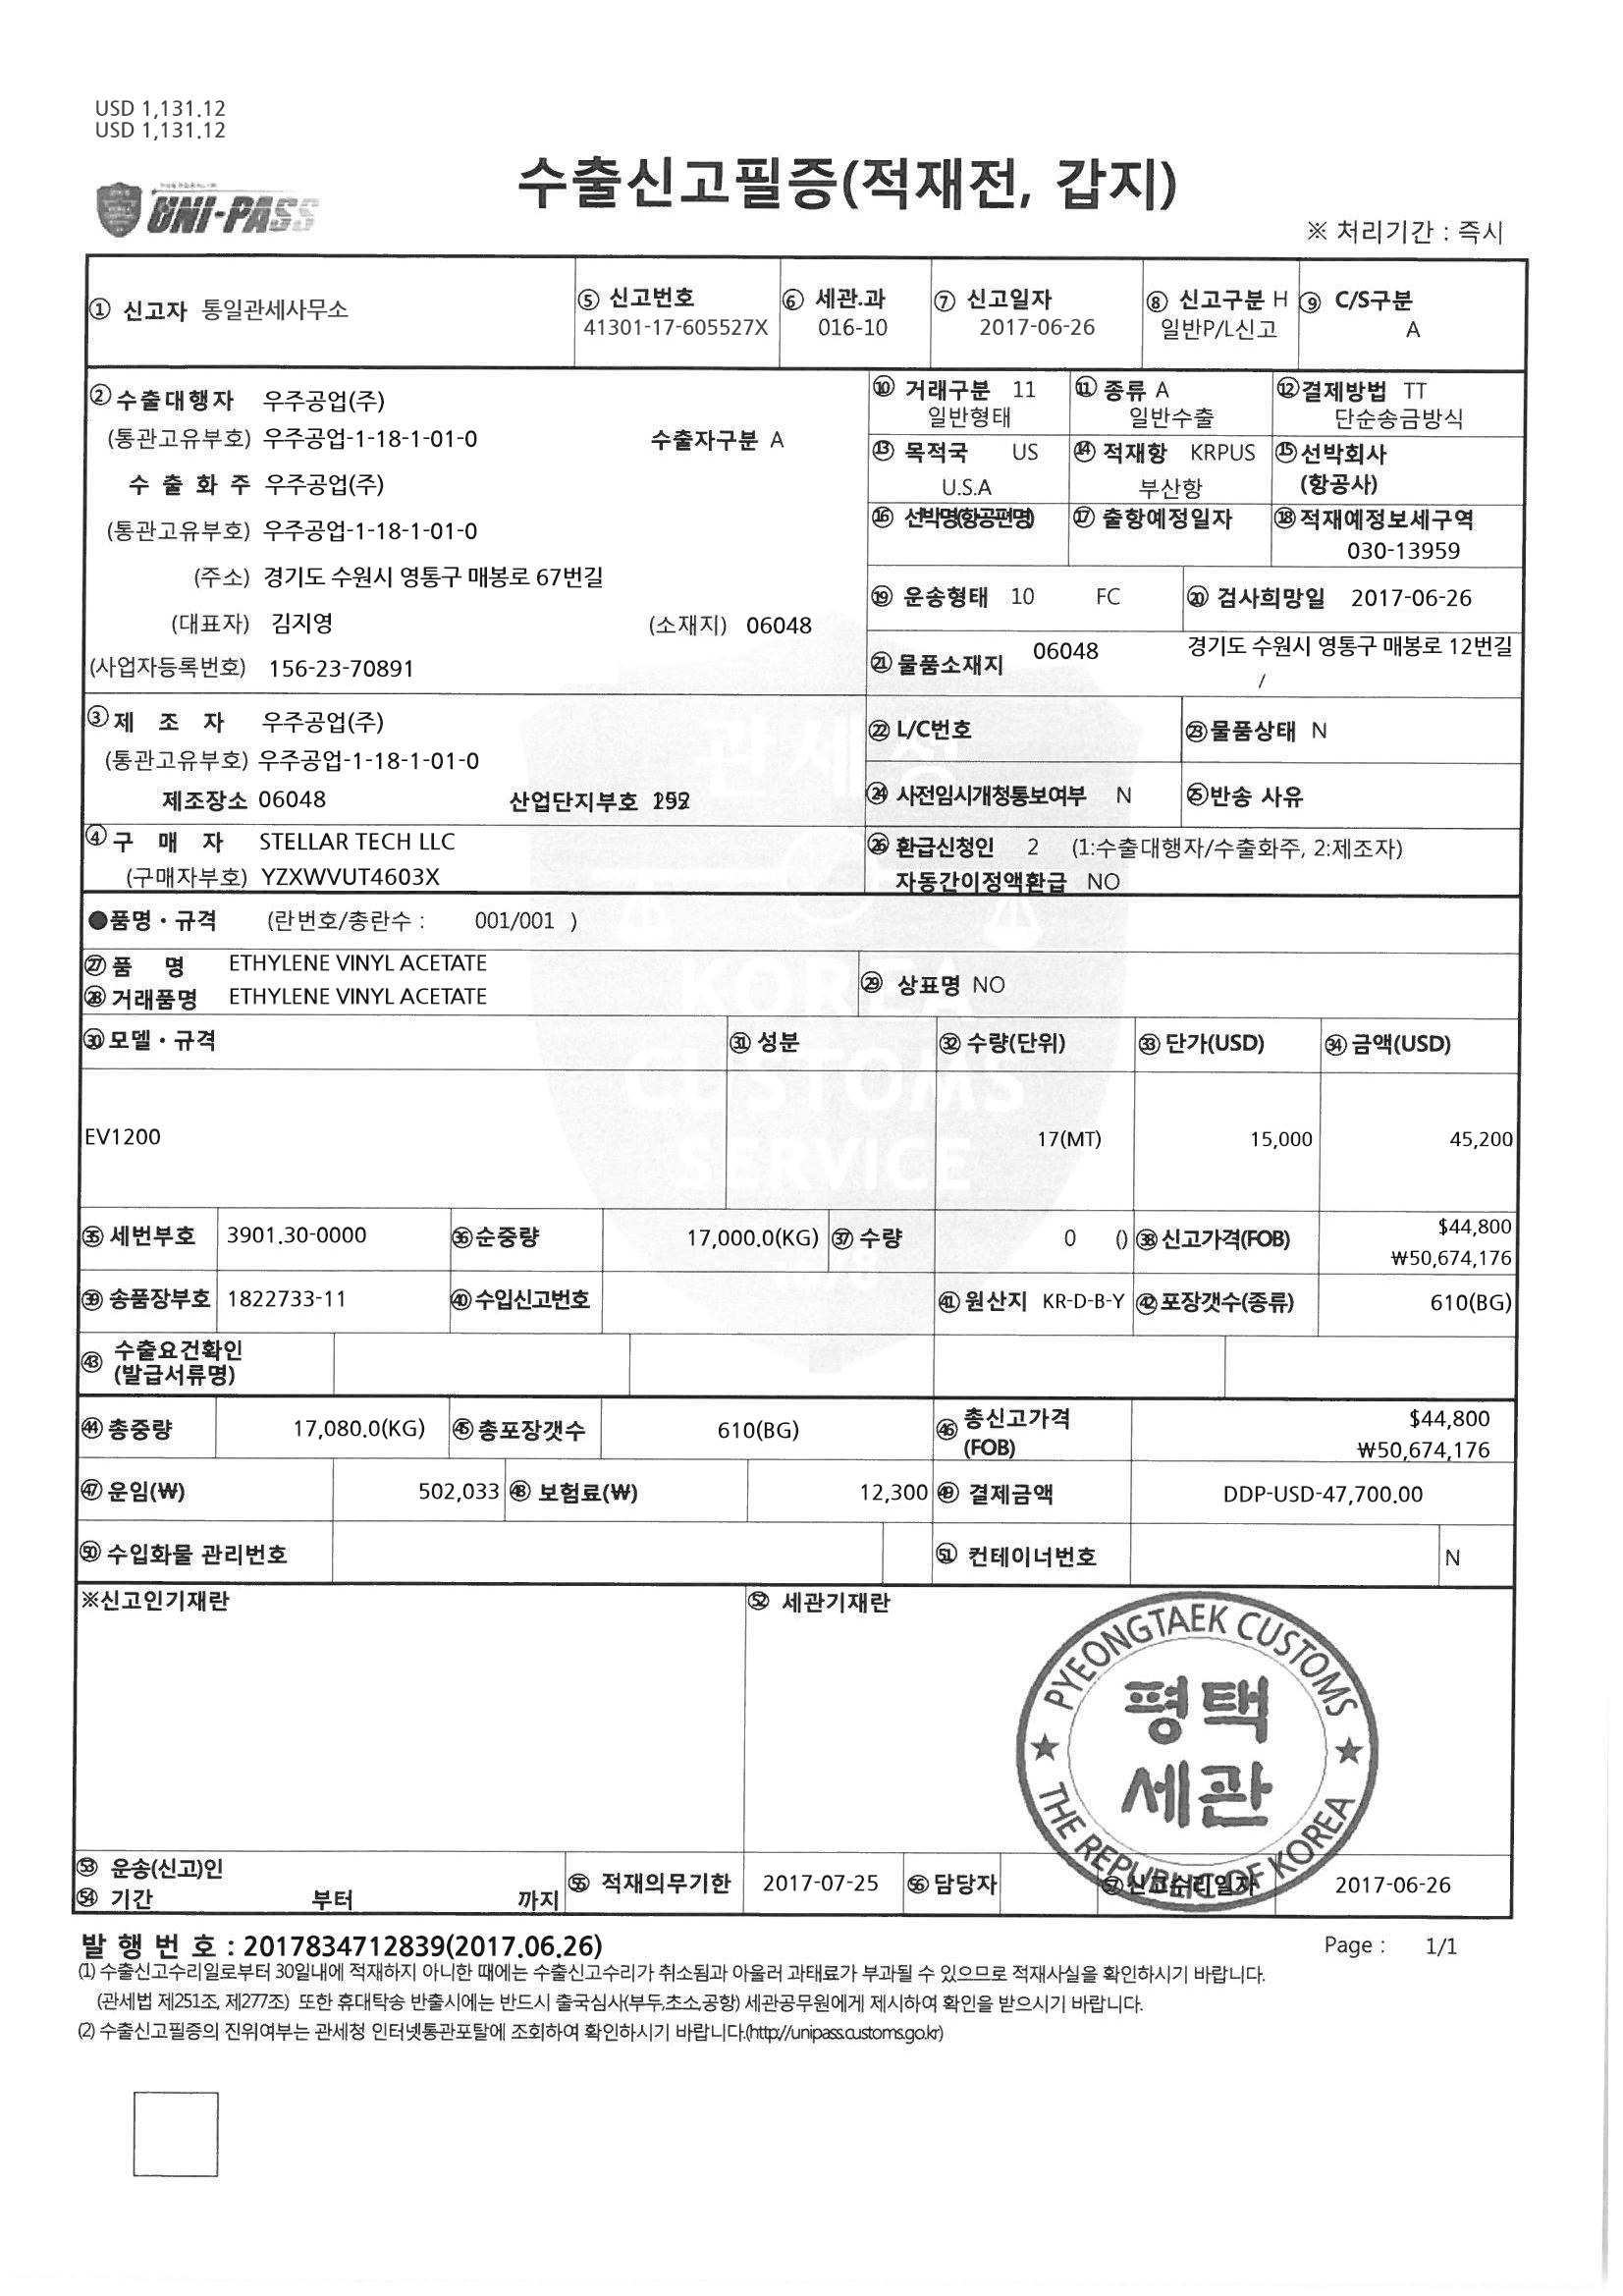 |
| Alias | commercial-invoice-and-packing-list-extraction | commercial-invoice-and-packing-list-extraction | kr-export-declaration-certificate-extraction |
| Currently points to | commercial-invoice-and-packing-list-extraction-250415 | commercial-invoice-and-packing-list-extraction-250415 | kr-export-declaration-certificate-extraction-250415 |
| RPS (Learn more) | 1 | 1 | 1 |
Don’t see your document type listed?
Contact us—we provide access to hundreds of private models for a wide range of document types, and offer high-precision custom model development to meet your specific business needs.
Extract Key Information in Upstage Studio!

Input requirements
- Supported file formats: JPEG, PNG, BMP, PDF, TIFF, HEIC, DOCX, PPTX, XLSX, HWP, HWPX
- Maximum file size: 50MB
- Maximum number of pages per file: 30 pages (For files exceeding 30 pages, the first 30 pages are processed)
- Maximum pixels per page: 100,000,000 pixels. For non-image files, the pixel count is determined after converting to images at a standard of 150 DPI.
- Supported character sets: Alphanumeric, Hangul, and Hanja are supported. Hanzi and Kanji are in beta versions, indicating that they are available but not fully supported.
Hanja, Hanzi, and Kanji are writing systems based on Chinese characters used in Korean, Chinese, and Japanese writing systems. Despite sharing similarities, they possess distinct visual representations, pronunciations, meanings, and usage conventions within their respective linguistic contexts. For more information, see this article.
Example
Request
Response
Extract Key Information in Upstage Studio!
Frequently Asked Questions
Check out frequently asked questions below. For more FAQs, visit the FAQ page.