Understanding the outputs
Layout categories and HTML tags
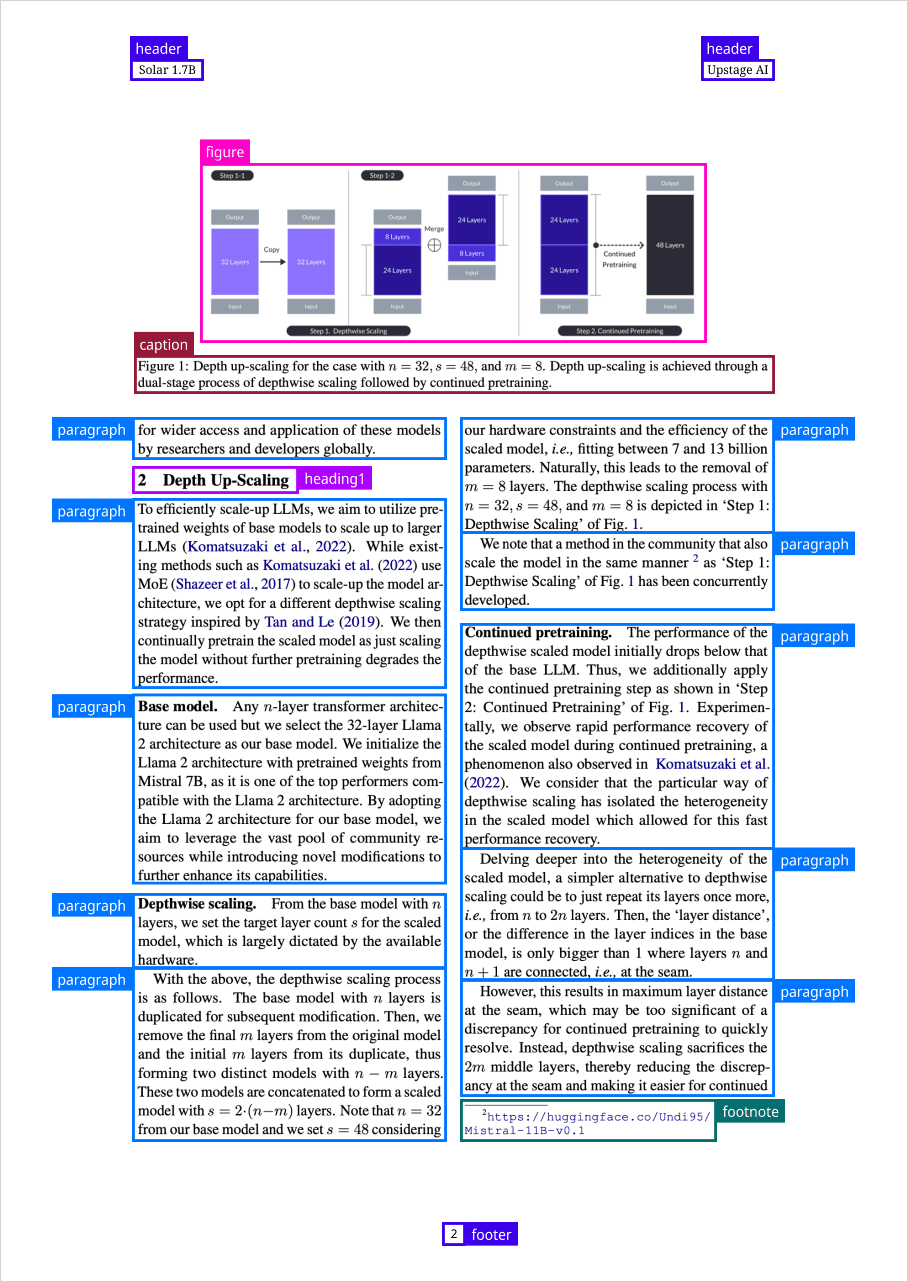
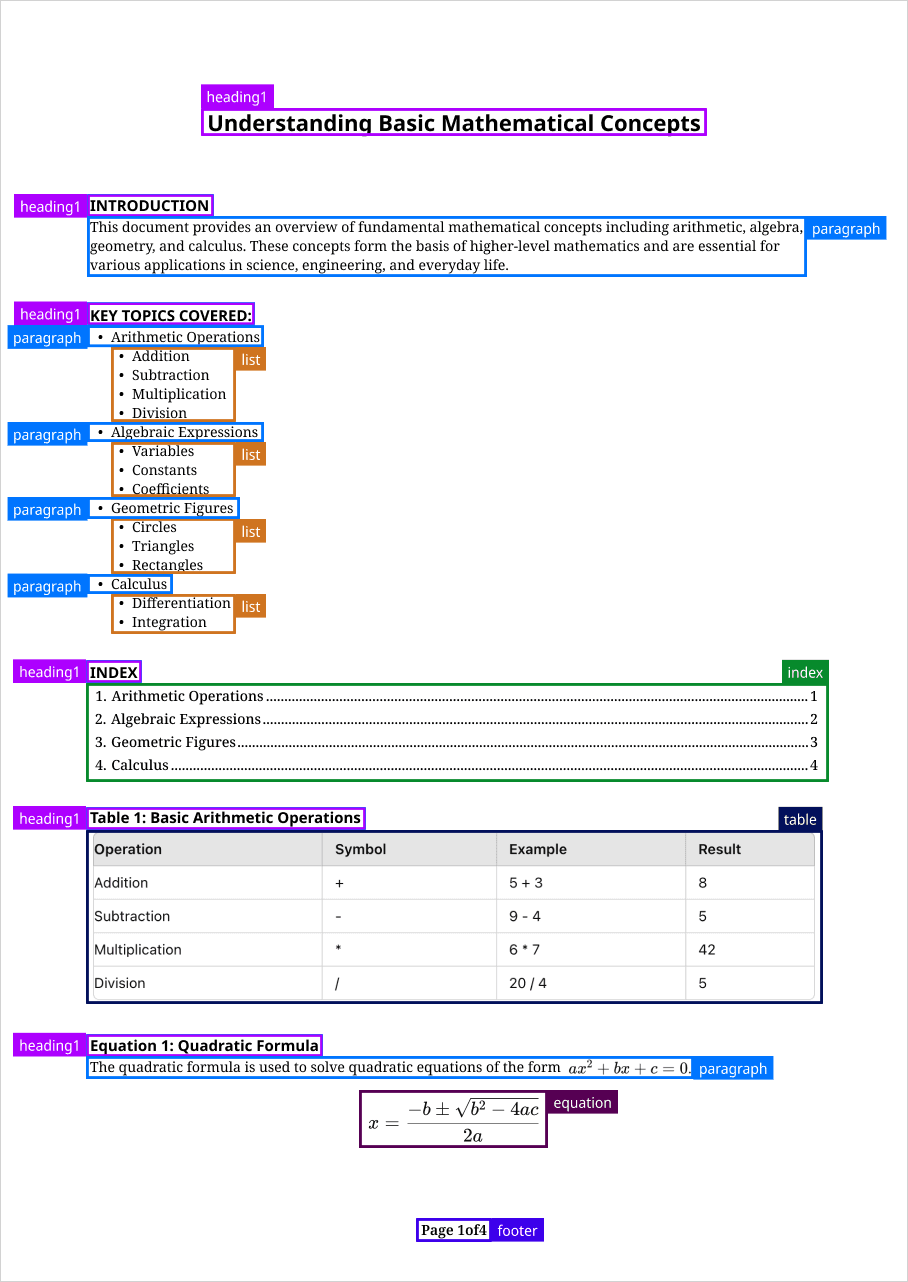
Upstage Document Parse identifies various layout categories in the input document and converts them to HTML tags.
The table below describes all layout categories and corresponding HTML tags.
If there is no suitable HTML tag for the layout category, it uses a <p> tag with a data-category attribute to explain the layout category detected by the model. list is the one exception — in enhanced mode on document-parse-260930 and document-parse-nightly (including pages that auto mode processes as enhanced), it returns a real <ul> or <ol> element with <li> items instead, and the list kind is available in the element's sub_category field (ul or ol).
| Layout category | HTML tag |
|---|---|
| table | <table> .. </table> |
| figure | <figure><img> .. </img></figure> |
| chart | <figure><img data-category="chart"> .. </img></figure> |
| heading1 | <h1>... </h1>; <h2> to <h6> by sub_category in enhanced mode on document-parse-260930 and document-parse-nightly |
| header | <header> .. </header> |
| footer | <footer> .. </footer> |
| caption | <p data-category="caption">..</p>; <caption> when the caption is placed inside a <table>, <figcaption> when it is placed inside a <figure> |
| paragraph | <p data-category="paragraph">..</p> |
| equation | <p data-category="equation">..</p> |
| list | <p data-category="list">..</p>; <ul>/<ol> + <li> in enhanced mode on document-parse-260930 and document-parse-nightly |
| index | <p data-category="index">..</p> |
| footnote | <p data-category="footnote"> </p> |
| code | <pre><code> .. </code></pre> |
Some elements also carry a sub_category field — a finer, open-ended classification within a category. For example, a figure may be a signature, stamp, qr_code, or bar_code; a chart may be a line, bar, or pie; a heading1 carries its heading level (h2 to h6, omitted for a level-1 heading); and a code block reports its programming language (such as python). The value set is open and grows over time, so treat sub_category as an arbitrary string rather than a fixed set of values. The field is omitted when the model does not provide a sub-classification. Heading levels, list kinds, and the code category come from the enhanced mode parser on document-parse-260930 and document-parse-nightly.
A detailed example of layout categories can be seen in the example below.
Equation recognition
For the equation category output, the model provides recognized text in LaTex format within the <p data-category="equation"> tag to ensure proper display using popular equation rendering engines like MathJax.
The output of a sample equation image can be seen below.

In the response, the content.html and content.markdown fields contain the recognized equation in LaTex format, while the content.text field contains the OCR result text.
Because the OCR model does not support equation recognition at the moment, the content.text field may not contain the correct equation text. For equation category, the OCR result in the content.text field is provided for backward compatibility.
Users may have difficulty rendering the content.html field value properly in their HTML file.
This is because the API response in JSON format escapes the \\ character. To resolve this issue, they can use JavaScript to unescape the HTML.
The example code below demonstrates how to render the equation properly in an HTML file by importing the MathJax library and unescaping the API response.
The sanitizer step also allows every tag and attribute Document Parse can emit across all layout categories (see the table above), not just the <p> tag this equation example uses — so other elements in your document aren't silently stripped.
Please note that users can also obtain the base64 encoded image of the equation from the original document by specifying ["equation"] in the base64_encoding field of the request body.
Four-decimal format coordinates
Since document-parse-240910, users can employ relative coordinates when drawing bounding boxes or cropping elements from input documents. The absolute position can be calculated by multiplying the x and y values in the coordinates field of each item by the width and height of the requested image.